59 or 8? How to Derive a V&V Sample Size You Can Defend
Design verification sample size rationale: binomial success-run vs. variables tolerance intervals.
"That's what we always use" will not survive an audit. This article walks through the two standard ways to derive a verification sample size you can defend. The first is the binomial success-run for pass/fail tests: 95/95 means 59 units with zero failures. The second is the variables tolerance interval with k factors per ISO 16269-6. A worked, fictional example shows both in practice, and an editable calculator and template are linked at the end.
The question behind the question
Every V&V engineer hears it in review: why this many units? The reviewer is rarely asking to learn statistics. They are asking because a sample size picked from habit is nearly impossible to defend. When an auditor, a notified body or your own design reviewer points at the number, "tradition" is not an answer. The number must be derived, documented and tied to risk before the test runs.
That derivation is a chain, and every link is written down:
- Attribute type. What does the test produce: a pass/fail verdict, a continuous measurement, or wear and lifetime behavior?
- Risk. Which harm does this requirement protect against, and how severe is it? Take severity from the risk analysis, not from an RPN score.
- Reliability and confidence target. What reliability R at what confidence C does that severity justify? Define the mapping once, in a procedure, before any project starts: a standing table from severity class to R/C target. A 95/95 target is common for significant risk, but it is not universal.
- Method and acceptance criterion. Only now do you choose the statistics, and you fix the acceptance criterion at the same time. It is never negotiated after the run.
If any link is missing from the document, the number is an opinion.
First, classify the attribute
The classification picks the tool, never the other way around. Deterministic logic, such as whether an output latches when its input crosses a threshold, is not a continuous measurement. A pass/fail verdict is not a cycle time. Wear calls for a reliability model, not a one-shot test.
Most defensibility problems start here. Either a continuous measurement is forced into a pass/fail plan and its information is thrown away, or a pass/fail attribute is dressed up with statistics it does not need.
Route A: attribute tests and the binomial success-run
For a pass/fail attribute with zero failures allowed, the minimum sample size that demonstrates reliability R at confidence C comes from the exact (Clopper–Pearson) one-sided bound:
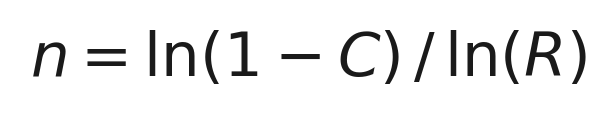
For 95% reliability at 95% confidence, n = ln(0.05) / ln(0.95) = 58.4, which rounds up to 59 units with zero failures. The number leaves no design freedom; it follows directly from the requirement.
| Target (R / C) | Units, zero failures |
|---|---|
| 90% / 90% | 22 |
| 95% / 90% | 45 |
| 95% / 95% | 59 |
| 99% / 95% | 299 |
| Two points are worth stating plainly in the review meeting: |
- What fewer units actually claim. Eight units with zero failures support only about 69% reliability at 95% confidence. That may be acceptable for a low-severity requirement, but say so, and cite the risk analysis that justifies it. Never let eight units pass silently as a 95/95 demonstration.
- This is not AQL sampling. Acceptance sampling plans (ISO 2859-1, ANSI/ASQ Z1.4) govern lot disposition in production: they answer "should this lot ship?", not "does the design meet its reliability requirement?" A reliability demonstration uses the success-run bound. Confusing the two is one of the most common findings in this area.
Reference: NIST/SEMATECH e-Handbook of Statistical Methods, section 8.1.3.2.
Route B: continuous measurements and variables tolerance intervals
A continuous measurement carries far more information per unit than a verdict, because every unit also tells you something about the variance. That information is what lets you reduce the sample size. Instead of counting failures, you show that a statistical tolerance limit stays inside the specification. For a one-sided upper specification:
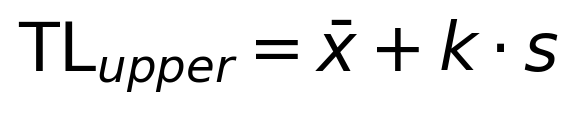
Here k is the one-sided normal tolerance factor for coverage P, confidence C and sample size n (ISO 16269-6:2014; the computation is described in the NIST e-Handbook, section 7.2.6.3). For P = 95% and C = 95%, k = 3.187 at n = 8. Provided the normality assumption holds, 8 units can support a 95/95 claim comparable to 59 pass/fail units. That proviso is the price of the smaller sample.
The real trade-off is sample size against margin. Fewer units means a larger k, so the process mean must sit further from the specification limit. Sample size is a design choice you trade against how much margin your process has:
| n | k (one-sided, 95/95) | Required margin to the limit |
|---|---|---|
| 8 | 3.187 | 3.19 s |
| 10 | 2.911 | 2.91 s |
| 15 | 2.566 | 2.57 s |
| 20 | 2.396 | 2.40 s |
| 30 | 2.220 | 2.22 s |
| A process with only 2.5 standard deviations between its mean and the limit cannot pass at n = 8, but it can at n = 20. | ||
| One-sided and two-sided k factors are different numbers. This example uses a one-sided upper specification. If the requirement has both a lower and an upper limit, the two-sided k factor is larger (about 3.73 at n = 8), and the sample size changes accordingly. The calculator linked below handles both and labels which one you are using. | ||
| The smaller sample comes with obligations, because you are now making a claim about a distribution: |
- Justify normality from more than the sample. At n = 8, a normality test (Anderson–Darling, Shapiro–Wilk) has almost no power to reject, so a "pass" proves little. Support the assumption with process knowledge or prior data from development builds or similar parts. Otherwise, transform the data or use a nonparametric method and accept the larger n.
- Show the measurement system can see the variation. Document MSA or gage R&R for the measurement.
- Make the sample represent production. Use different lots, operators and edge conditions. Eight units from one good run underestimate s, which makes the tolerance limit optimistic.
Worked example (fictional)
A fictional component has an upper specification limit (USL) of 45 N on its critical output force. A verification run of n = 8 units gives a mean of 40.2 N and a standard deviation of 1.3 N. For a one-sided 95/95 claim:
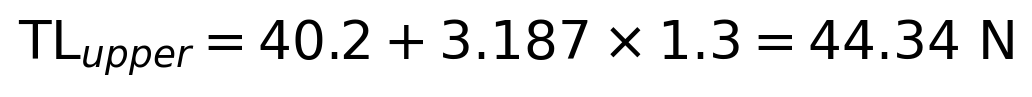
The tolerance limit of 44.34 N is below the 45 N USL, so the test passes. Put another way, the mean sits 3.69 standard deviations below the limit, more than the 3.19 required at n = 8.
The margin is only 0.66 N, so the result is close to the limit. Confirm that measurement uncertainty is small relative to that margin, and apply a guard band if your procedure calls for one.
The rationale document records the full chain: the attribute classification, the risk link that set 95/95, the choice of a one-sided method, the k factor and its source, the raw data, and the tolerance-limit calculation. That document, not the number 8, is what survives the audit.
After the number
The calculation alone is not enough, and a single failure is not a reason to reach for a bigger sample. If a unit fails, investigate the root cause first. Enlarging the sample until the test passes is not statistics; it is shopping for a result, and reviewers recognize it.
The honest options are:
- Fix the cause and rerun.
- Reassess whether the requirement or the method was correct.
- Accept a lower demonstrated reliability and tie it back to risk, openly and in writing.
This is different from a plan that allows failures from the start. Planning for one allowable failure (c = 1) is legitimate, provided it is fixed before the run: for 95/95 it requires 93 units instead of 59. What is not legitimate is changing the plan after you see the result.
Where this sits in the regulations
ISO 13485:2016 does not set a sample size, but it does require you to justify one. Clauses 7.3.6 (design verification) and 7.3.7 (design validation) require plans that include methods, acceptance criteria and, as appropriate, statistical techniques with a rationale for sample size.
Since February 2, 2026, the FDA's Quality Management System Regulation (QMSR) has incorporated ISO 13485:2016 by reference, so the same expectation applies to devices sold in the US. Neither document prescribes a number, and that is deliberate. What they require is a method that is defined, justified and documented. The derivation chain above is that justification, in a form a reviewer can sign.
Tools
- Free: the T-100 Evidence Checklist. A checklist of document ownership and required evidence for design verification. Download it here (email required): https://files.instinct.com/lmot4aoltu5z-free-t-100-evidence-checklist
- Sample Size Rationale Toolkit ($29). Includes the editable calculator (attribute and variables routes, one- and two-sided), a method guide, and a rationale template with the references already written in: https://npitoproducer.gumroad.com/l/sample-size-rationale
- The two-minute video version of this article: https://www.youtube.com/watch?v=FW_AUzfDf4E. Subscribe to the channel for the next articles in the series: https://www.youtube.com/@NPItoProductGuy
Everything above is an engineering aid. The example is fictional and marked as such. Adapt the methods to your product, and have a qualified professional review your adaptation. This article is not a compliance determination.